Your databases, up and optimized. Around the clock.

Free to start · No credit card required ·

Your production databases shouldn't keep you up at night. NeverBlink's AI works around the clock to find what to tune, fix and right-size, and shows its reasoning so your team stays in control.

NeverBlink Health Assessment for an Elasticsearch cluster: overall score 81 and rising, category scores for stability, performance, resiliency and security, a 30-day health history, and failing checks with recommendations

Trusted in production by engineering teams at

See customer results

AI is breaking the database.

There are more databases, more AI-generated workloads, and fewer people who know how to keep them healthy. Agents query constantly and ship sloppy SQL. Product engineers now own the data layer, usually on top of their day job.

89%

of teams building with agents now let them write to the database, up from 52% a year earlier.

Source: Amplify Partners, 2026 AI Engineering Report
0.4%

of developers call themselves a DBA. Over half run PostgreSQL. The role vanished, the databases didn't.

Source: Stack Overflow Developer Survey 2025
84%

of organizations have already had an AI-related outage.

Source: PagerDuty AI Resilience Survey, 2025

Beyond the legacy way of doing things.

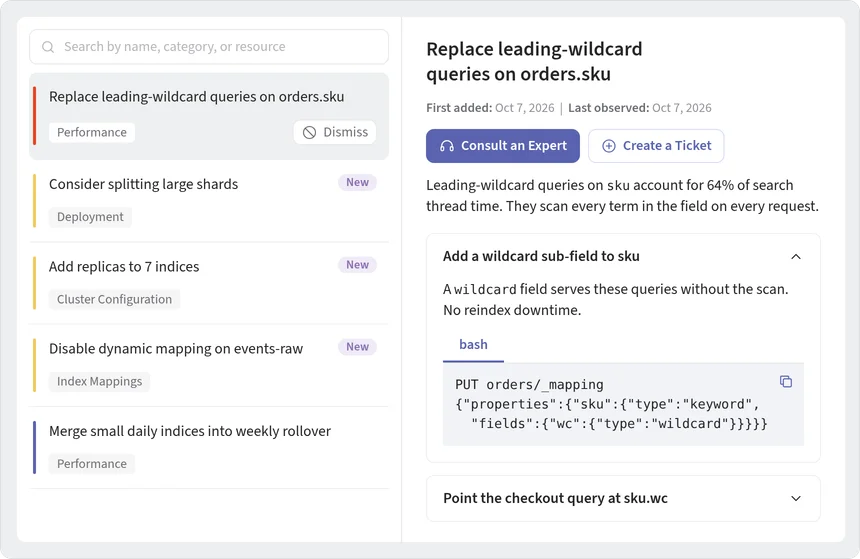
NeverBlink looks at the infrastructure and at how your application uses the database, and tells your team what to fix, in what order, with the command to run. Not another dashboard.

How NeverBlink compares with other ways of maintaining production databases
Capability NeverBlink Do nothing Monitoring only Managed cloud Hire a DBA Consultants
Spots problems early Yes No Partly Partly Partly No
Finds the root cause Yes No No No Yes Yes
Catches AI slop Yes No No No Partly Partly
Can lower bills Yes No No No Partly Partly
Covered 24/7 Yes No Partly Partly No No
What it costs you From $29per cluster / month Incidents Engineer hours Tuning is on you A salary Hourly bills

Continuous maintenance, run by an AI that knows each engine's internals.

NeverBlink recommends. Your engineers apply. Every finding comes with its evidence and the exact change.

Explore the platform

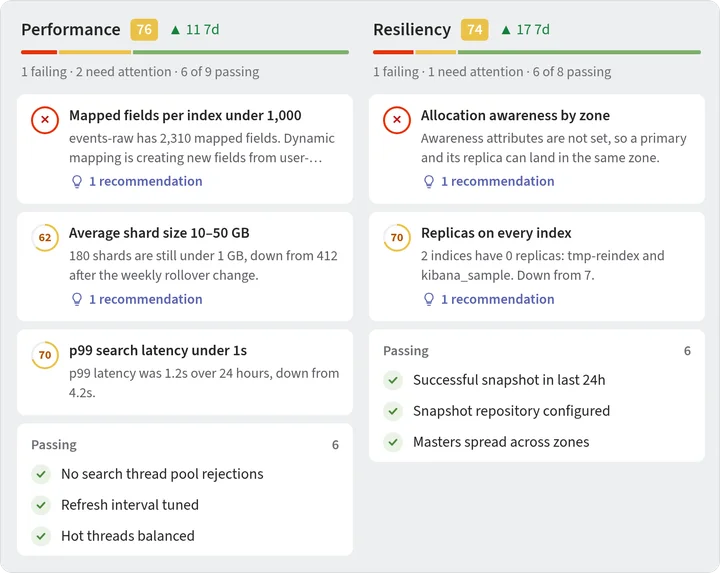
Performance and Resiliency health checks, with failing checks such as search thread pool
            rejections and failed snapshots, each linked to a recommendation

Built for your team, and for the agents they build with.

Coding agents now write queries, change schemas and ship at machine speed. Give them the same live context your engineers use, so they reason from evidence about your data platform instead of guessing. They propose; your team approves.

Claude CodeCursorCodexAny MCP client

A UI built for the team

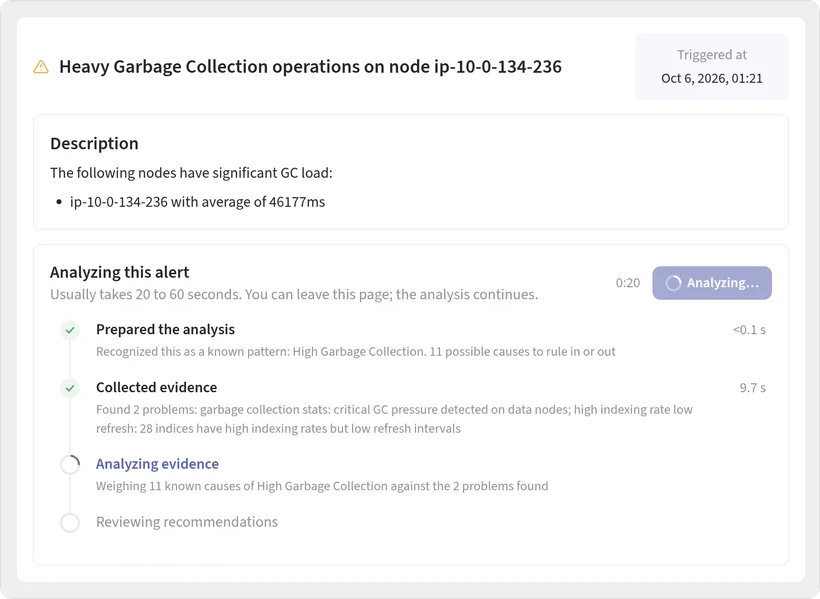
Cluster health, recommendations, alerts and root-cause analysis in one place.

REST API and MCP server

Pull health, alerts and recommendations into your workflows, CI and internal tools.

Signals for agents

Agents ask what changed, see the evidence, and propose a fix. Engineers stay in control.

AI does the watching. Senior engineers are a message away.

Databases are mission-critical, so NeverBlink never guesses and never acts alone. It pairs engine-specific AI with the BigData Boutique team, who have spent 15+ years running and rescuing these systems in production.

A 24/7 AI DBA

An AI DBA watches every cluster around the clock. When an issue needs judgment, a senior database engineer picks it up.

We've seen it all

The most complex clusters, self-hosted at any scale, and every major managed service.

Tailored to your size

Use the platform on its own, or add a 24/7 expert SLA and unlimited consulting.

Less work. Lower bills. Fewer pages.

Numbers reported by customers in the case studies below.

25–30%
lower database costs (Frontiers, Aidoc)
80–90%
less time spent managing databases (Frontiers, Aidoc)
70%
faster incident detection (Frontiers)
Zero
incidents since onboarding (Aidoc)
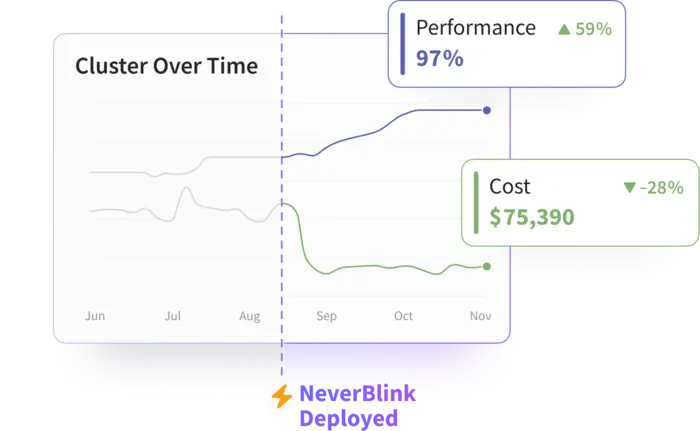
Cluster over time: after NeverBlink was deployed, performance rose 59% to 97% while monthly cost fell 28% to $75,390

Trusted in production at scale

Engineering and platform teams rely on NeverBlink to keep mission-critical databases stable, efficient and under control as scale and complexity grow.

Frontiers

Global research publisher running 11 self-hosted Elasticsearch clusters needed expert support and unified monitoring to replace fragmented tooling. NeverBlink delivered proactive health assessments, 24/7 expert guidance and one view across every cluster.

Key results
  • 80% less time managing Elasticsearch
  • 70% faster incident detection
  • 25% cost savings
Read case study

Aidoc

AI-powered radiology provider needed reliable OpenSearch monitoring across US and EU environments. NeverBlink replaced custom dashboards and manual checks with automated insights, single-pane visibility and expert guidance.

Key results
  • 90% less time managing OpenSearch
  • Zero incidents since onboarding
  • 30% cost savings
Read case study

LinearB

ClickHouse powers the real-time analytics behind LinearB's customer-facing dashboards. NeverBlink provides continuous insights on queries and node sizing and walks the team through each optimization.

Key results
  • Dashboard queries from 8 seconds to subsecond
  • Lower memory footprint and pipeline latency
  • Continuous query and sizing insights
See the ClickHouse story

AI product discovery platform

Search for 100+ leading brands and tens of millions of users runs on OpenSearch. When their observability vendor dropped OpenSearch support, NeverBlink stepped in with OpenSearch-specific monitoring, daily health reports and 24/7 experts.

Key results
  • 95% less troubleshooting time
  • 70% better key performance metrics
  • 40% total cost savings
Read case study

Connected in minutes. Paying for itself in 30 days.

1
Minutes

Connect

A lightweight collector runs in your environment, on Kubernetes, Docker, ECS, Nomad or a VM, with a read-only monitoring user. Nothing is installed on your database servers.

2
Within 24 hours

Analyze and report

Your first prioritized findings arrive with the reasoning, in Slack, email or PagerDuty, and through the API and MCP.

3
Continuous

Optimize

Queries, merges, replication, schema and configuration are inspected continuously. Fixed issues clear themselves.

✓
Day 30

Self-sustaining

Regressions are caught as they appear, and your team spends its time on the product instead of the database.

SOC 2 Type II

Security controls independently audited over time.

Never reads your rows

Metrics and metadata only. Query literals are masked at ingestion.

Nothing on DB servers

The collector runs in your network with read-only access you control.

Enterprise ready

SSO and SAML, RBAC, agent IP allow-listing. AWS Advanced Consulting Partner.

How NeverBlink handles your data →

Questions engineers ask first

More in the docs.

Will NeverBlink change my cluster?

No. NeverBlink never changes your cluster on its own. It hands you the fix, with the exact command, and your engineers decide what to apply. Every recommendation shows its evidence, and every applied change is yours to audit.

Is NeverBlink a monitoring tool?

Monitoring tells you something changed. NeverBlink tells you why, whether it matters, and what to do about it. It has dashboards too, but the core of the product is continuous health checks, root-cause analysis and prioritized recommendations, backed by engineers who can step in.

Does NeverBlink access my data?

No. The collector reads operational metrics, system tables and metadata through a read-only monitoring user. It never reads, transmits or stores the rows in your databases. Query Analytics masks literal values before they reach NeverBlink.

Does it work with managed services?

Yes: Elastic Cloud, Amazon OpenSearch Service, ClickHouse Cloud and Amazon RDS for PostgreSQL. A managed service keeps the servers running. It doesn't fix slow queries, poor schemas or overprovisioning, and that is the layer NeverBlink covers.

How long does setup take?

Minutes. Create a monitoring user, run the collector with your ingest key, and the first health assessment arrives the same day.

How is NeverBlink different from a general AI SRE tool?

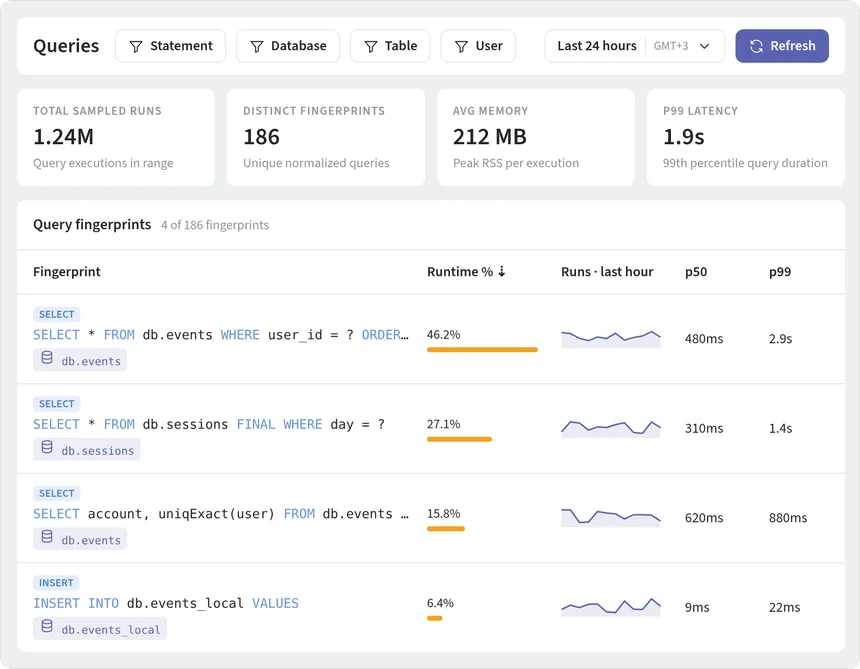
NeverBlink is built only for databases, one engine at a time. Its checks and recommendations come from years of running these specific engines in production, so the advice reflects how each engine actually works. A general tool tells you to check the slow query log. NeverBlink finds the query shape, explains why it is expensive and hands you the rewrite.

See what your cluster isn't telling you.

Add your first cluster free, or get a full health assessment and walk you through the findings within 24 hours.

Subscribe to the NeverBlink Newsletter

Get early access to new NeverBlink features, insightful blogs & exclusive events , webinars, and workshops.

We use cookies to provide an optimized user experience and understand our traffic. To learn more, read our use of cookies; otherwise, please choose 'Accept Cookies' to continue using our website.